Categorical Cut on a Continuous Distribution
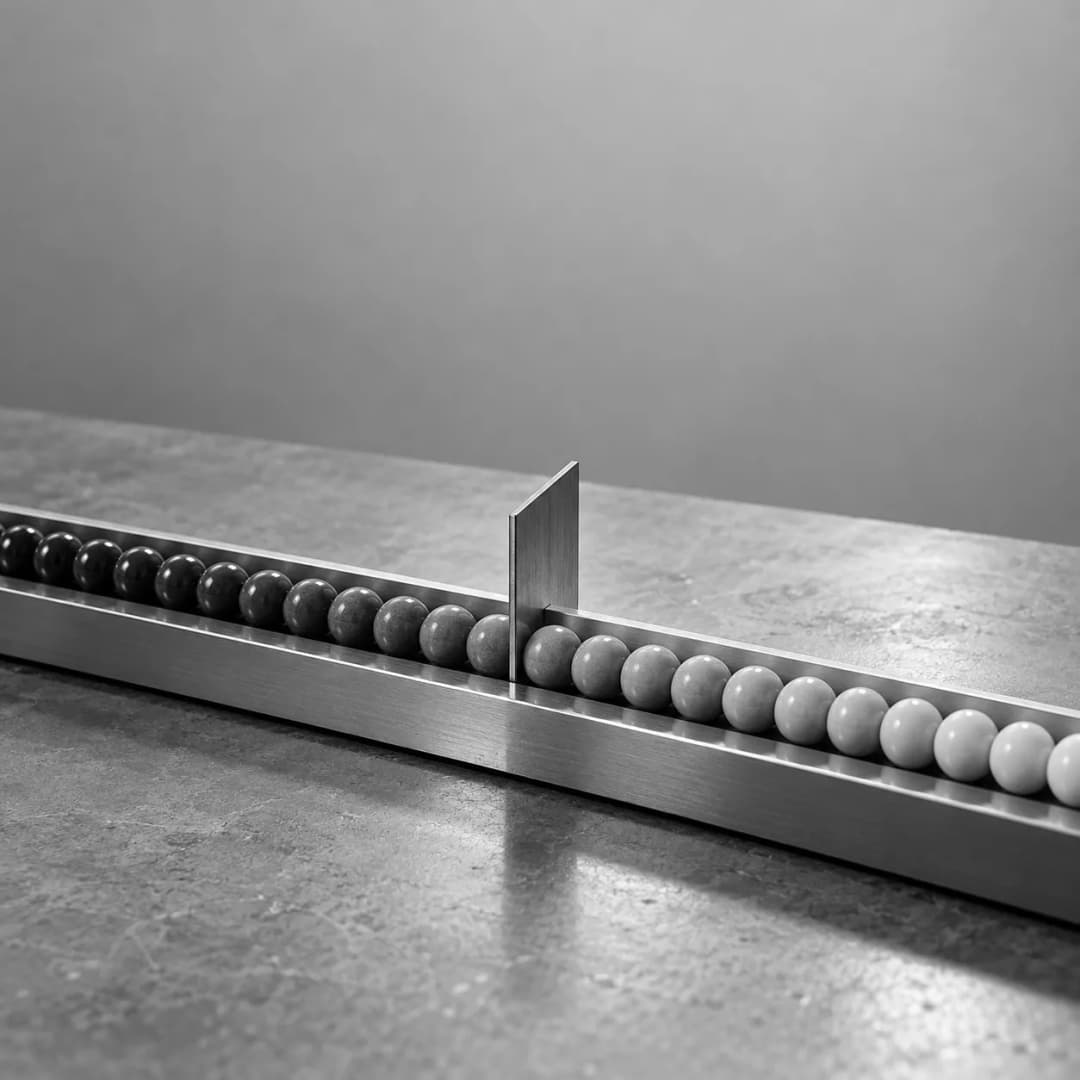
This is the technical reason type-based segmentation fails even where the scales underneath it are reliable. If a continuous trait is split into two categories at a cut point, everybody sitting near that cut flips category on a small amount of ordinary measurement noise, however well the underlying scale measures. The fault is in the cut, not in the measurement, and saying it that way is more damaging to the instruments involved than calling them horoscopes.
What it is
The clearest worked case is the Myers-Briggs Type Indicator. Robert R. McCrae and Paul T. Costa compared its four indices against the five-factor model and found no support for the view that it measures truly dichotomous preferences or qualitatively distinct types, concluding instead that it measures four relatively independent dimensions. The half of their verdict that commercial segmentation never quotes is the positive one, that those four indices do measure aspects of four of the five major dimensions of normal personality. Robert M. Capraro and Mary Margaret Capraro's reliability generalisation study then found that the instrument and its scales yielded scores with strong internal consistency and test-retest reliability, with variation observed.
In effect
Those two findings are not in conflict and the tension between them is the whole point. A reliable continuous scale and an unstable four-letter type are exactly what you would expect once a category boundary is drawn through the middle of a distribution, because the type reported to the user discards the distance from the cut, which is the only information that would tell you how stable the answer is. David J. Pittenger's caution is pitched at precisely the right level, attaching not to the instrument in general but to inferences drawn from the four-letter type formula. The same logic applies to any commercial segmentation that converts a measured continuum into a named customer type and then reports only the name.
What it does not say
It does not say the underlying scales are unreliable. The only meta-analytic reliability synthesis in reach says the opposite at scale level, and an argument that quotes only the critics has the story the wrong way round. It does not supply a figure for how often a type changes on retest: that is the most-quoted statistic about the instrument in existence and no version of it could be verified at a published record, with searches returning only blogs and commercial personality-test sites attributing figures to Pittenger without a page, so none is printed here. And it is not an argument against measuring personality, only against reporting a continuum as though it were a kind.
Sources
- McCrae, R. R., & Costa, P. T. (1989). "Reinterpreting the Myers-Briggs Type Indicator From the Perspective of the Five-Factor Model of Personality." Journal of Personality, 57(1), 17-40. doi:10.1111/j.1467-6494.1989.tb00759.x. Abstract read in full; the paper is closed and the specific correlations the vault holds are not in the abstract, so none is printed here.
- Capraro, R. M., & Capraro, M. M. (2002). "Myers-Briggs Type Indicator Score Reliability Across Studies: A Meta-Analytic Reliability Generalization Study." Educational and Psychological Measurement, 62(4), 590. doi:10.1177/001316402128775030. The deposited DOI is the one given; a commonly printed one redirects. Crossref deposits the first page only.
- Pittenger, D. J. (2005). "Cautionary comments regarding the Myers-Briggs Type Indicator." Consulting Psychology Journal: Practice and Research, 57(3), 210-221. doi:10.1037/1065-9293.57.3.210. The caution attaches to inferences from the four-letter type formula.
- Pittenger, D. J. (1993). "The Utility of the Myers-Briggs Type Indicator." Review of Educational Research, 63(4), 467-488. doi:10.2307/1170497. Crossref deposits the first page only.
- Stein, R., & Swan, A. B. (2019). "Evaluating the validity of Myers-Briggs Type Indicator theory: A teaching tool and window into intuitive psychology." Social and Personality Psychology Compass, 13(2), e12434. doi:10.1111/spc3.12434. A theoretical and pedagogical review with no sample and no test, cited for the three theoretical failures the authors name.