Information Cascades
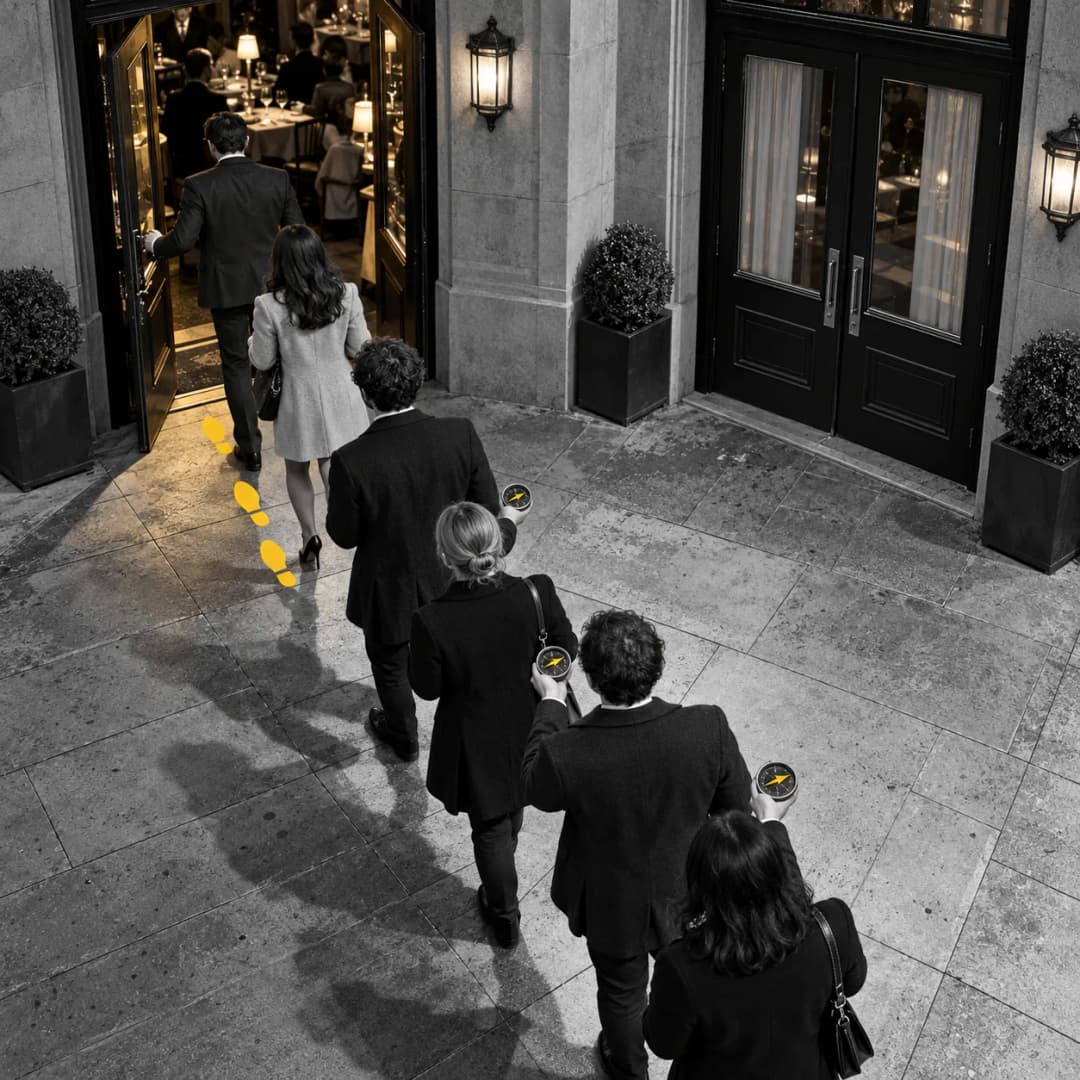
An information cascade is the point at which somebody who can see what others chose, but not why, correctly stops using what he knows himself and copies instead. His choice then carries no information about his own signal, so everybody behind him learns nothing from it, and a very large crowd can rest on the first two or three judgements made in it. Sushil Bikhchandani, David Hirshleifer and Ivo Welch named the mechanism in 1992, and Abhijit Banerjee reached the same result independently the same year.
What it is
Picture a street with two restaurants on it. You have read something that mildly favours the second one. You arrive and see two people already seated in the first. Nothing about them tells you what they know, but the fact that they chose is itself a piece of evidence, and if your own information is weak enough, the sensible thing is to conclude that they may know something and to join them.
That is the whole mechanism, and the interesting part is what happens next. Once you copy, your choice no longer reports your private information. The person arriving behind you sees three people in the first restaurant and cannot tell whether that reflects three independent judgements or one judgement followed by two acts of deference. So he faces the same calculation you did, with the same answer, and the queue grows on the strength of the signals that went into it before the pinch point.
Two things follow that are easy to miss. The first is that nobody in this story is reasoning badly. Each person does the optimal thing with what is in front of them. The second is that the crowd is nonetheless carrying far less information than its size suggests. Michelle Baddeley's walkthrough in Copycats and Contrarians locates the whole cascade in a single individual at a knife edge, which is a useful corrective to the image of mass behaviour as a mass phenomenon. It is often one person's decision, repeated.
The four conditions
The result is a theorem, and like every theorem it needs its assumptions. Each of the four is an empirical question about a particular situation rather than a fact about the world.
Sequence. People choose one after another, and later choosers can see earlier choices. Simultaneous choice produces no cascade, because there is nothing to observe.
Choices observable, reasons not. You can see that they went in. You cannot see why. If reasons were visible there would be nothing to infer and no cascade to form.
Independence of the early signals. The information content of a crowd depends entirely on the first few people having looked at the thing themselves. This is the condition that decides everything and the one almost nobody can check.
Comparable preferences. Their good choice has to be a good choice for you. A crowd of people with different budgets, tastes or constraints is weaker evidence than a crowd of people like you.
When all four hold, copying is the correct inference and should be described that way without hedging. When one fails, copying is the mistake the word herding implies, and the one that fails is usually independence.
Fragility, which is a prediction rather than a complaint
Because the crowd rests on very few signals, it is unstable in a way its size disguises. A small amount of contrary public information can turn it over. A fad that took a thousand people to build can be destroyed by one credible dissenter, and this is a prediction of the rational model rather than an observation about human weakness.
Bikhchandani, Hirshleifer and Welch concede the limit of their own result here, as Baddeley records: the model cannot say when the flip arrives. It explains why mass behaviour is fragile without predicting the moment of reversal, which is the part anybody standing inside a bubble actually wants to know.
In effect
The urn game, where the right answer was known in advance
Lisa R. Anderson and Charles Holt took the structure into a laboratory in 1997. Private signals were draws from an unobserved urn, subjects announced predictions in sequence, and they were paid for guessing correctly, so following the crowd carried a price rather than being free. Because the urn structure fixed the Bayesian answer for every participant at every point, rational here is a calculation rather than a judgement call. Their reported result is that rational cascades formed in most periods in which an early imbalance appeared.
The honest reading, which the article behind this page states, is that the behaviour replicates and the interpretation does not. The paper is flagged at its RePEc record as replicated by Hung and Plott in 2001, a record read for the replication's existence and title only. Separately, several lines of work argue that what looks like Bayesian updating is a simpler rule of thumb that mimics it in this particular design. None of that challenge literature was read at source here and none of its figures appears on this page. Baddeley makes the same point in her own voice: the findings have been replicated widely while few replications rigorously tested alternative hypotheses.
Choosing a restaurant on an unfamiliar street
The everyday case is the one the theory was built to explain, and the four conditions do real work in it. People do choose in sequence, and a full room is visible from outside, so the first two conditions hold almost always. Comparable preferences usually hold on a street where everybody is looking for dinner.
Independence is the one to test, and it is testable in practice by a single question: did the people ahead of me look at the thing itself, or did they look at each other? A queue formed by people who each read reviews, checked a menu and made a judgement is genuine evidence. A queue formed because the first group arrived early and the rest saw a queue is a cascade carrying almost nothing. From the pavement, the two look identical. That is not a failure of attention on the part of the person on the pavement. It is the structural feature the model describes.
A ranking widget on a shopping page
Commerce builds cascade machinery deliberately. A bestseller list, a most-popular tab, a download counter and a trending shelf all publish earlier choices to later choosers while publishing nothing about the reasons behind them, which is condition two implemented as a product feature.
Whether that machinery transmits information or manufactures it depends on condition three, and the firm running it is the only party who can tell. Hongbin Cai, Yuyu Chen and Hanming Fang's 2009 restaurant experiment is the good case: the ranking information came from the restaurant's own order records, so it was an accurate report of what people had chosen, and demand for the listed dishes rose by 13 to 20 per cent with no significant effect from merely naming sample dishes. Ward A. Hanson and Daniel Putler's 1996 field experiment is the warning: download counts on a live commercial service were inflated by repeated downloading, applied to one member of each matched program pair at randomised levels, and substantial additional downloads followed. Substantial is their word, and no magnitude is printed here, because the body of that paper is paywalled and was not read. Their closing call, for verifiable online popularity measures, was made in 1996.
What it does not say
It does not say that people are gullible, irrational or weak. The mechanism's whole point is that it runs on correct reasoning, and an account of herding as a failure of nerve is not this account.
It does not say that the crowd is wrong. A cascade can settle on the better option, and often will if the early signals were good. Baddeley's contribution, recorded in detail on the page for rational herding, is that the cost arrives anyway, because the private information discarded along the way is lost to everybody behind the pinch point.
It does not tell you when a crowd will turn. The original authors say so themselves.
And it does not establish that real crowds form by Bayesian updating. That the behaviour appears in the laboratory is well supported; that the arithmetic inside the copier matches the model is contested, and nothing on this page settles it. The evidence here is graded primary-cited rather than robust for a specific reason: no full text was obtained for any of the twelve journal articles behind the article that uses this concept. The 1992 Journal of Political Economy paper deposits no abstract at Crossref at all, so its content reaches this site through the vault's reading of Baddeley and through search summaries, and not through a reading of the paper. Several secondary summaries attach precise probabilities to that paper, and none was verified at source, so none appears here.
Who developed it
Sushil Bikhchandani is first author of the 1992 Journal of Political Economy paper that named the informational cascade, with David Hirshleifer and Ivo Welch. Abhijit V. Banerjee published a sequential model reaching the same conclusion in the Quarterly Journal of Economics in the same year, independently. Lisa R. Anderson is first author of the 1997 laboratory test, and Michelle Baddeley wrote the exposition this site relies on for the mechanism.
Sources
- Bikhchandani, S., Hirshleifer, D., & Welch, I. (1992). "A Theory of Fads, Fashion, Custom, and Cultural Change as Informational Cascades." Journal of Political Economy, 100(5), 992-1026. doi:10.1086/261849. Crossref record read in full; no abstract is deposited for this paper. Title, journal, volume, pages and author order confirmed at source. The model's content reaches this site through the vault's reading of Baddeley (2018) and through search summaries, and not through a reading of the article.
- Banerjee, A. V. (1992). "A Simple Model of Herd Behavior." Quarterly Journal of Economics, 107(3), 797-817. doi:10.2307/2118364. Abstract read in full at the RePEc record. Full text restricted and not read.
- Anderson, L. R., & Holt, C. A. (1997). "Information Cascades in the Laboratory." American Economic Review, 87(5), 847-862. Abstract read in full at the RePEc record. Full text not read.
- Hung, A. A., & Plott, C. R. (2001). "Information Cascades: Replication and an Extension to Majority Rule and Conformity-Rewarding Institutions." American Economic Review, 91(5), 1508-1520. Bibliographic record only, read at the replication field of the Anderson and Holt item. Not read, and nothing substantive is attributed to it.
- Cai, H., Chen, Y., & Fang, H. (2009). "Observational Learning: Evidence from a Randomized Natural Field Experiment." American Economic Review, 99(3), 864-882. doi:10.1257/aer.99.3.864. Abstract read in full, reconstructed from the OpenAlex inverted index, so nothing from it appears here inside quotation marks. Full text not read.
- Hanson, W. A., & Putler, D. S. (1996). "Hits and misses: Herd behavior and online product popularity." Marketing Letters, 7(4), 297-305. doi:10.1007/BF00435537. Abstract and complete reference list read at the publisher's article page. Body text paywalled and not read, so no magnitude is printed.
- Baddeley, M. (2018). Copycats and Contrarians: Why We Follow Others ... and When We Don't. Yale University Press, chapter 1, pp. 17 to 30. Read in full by the vault in October 2026. A trade book rather than a peer-reviewed source, cited for exposition and for the primary literature it attributes correctly, and not for any figure.